Agentic video understanding in Gemini
▶ Watch on YouTube · Google for Developers · 3:19
Processing long videos can use a lot of tokens. Learn how to do this more efficiently using our latest agentic video understanding capability available in Gemini 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite. In this video, Google DeepMind’s Maarten Grootendorst explains how agentic video understanding works, and how this approach reduces token costs while improving accuracy on the parts of the video that actually matter.
— Channel description, Google for Developers
A 3-minute technical explainer by Maarten Grootendorst of Google DeepMind, describing a capability shipped in the Gemini Flash line: instead of passing a video to the model as payload, pass a reference to it plus tools, and let the model run an agentic loop that fetches only the parts it needs.
Short, but it earns a source page because it is the cleanest small statement in the corpus of a principle the wiki holds in many long-form versions: give the model a handle and the means to fetch, not the whole artifact — and because it reports the counterintuitive half of that claim, that fetching less improves accuracy rather than trading it for cost.
TL;DR
- The naive baseline and its cost. The standard approach splits a video into frames and passes them all: “If we give the entire video to Gemini, there will be already more than 100,000 tokens. That’s a lot, and there’s a lot of information that we really don’t need — because what if I only want information in frame 900, or a couple of seconds here, a couple of seconds there?”
- The move: a reference plus tools instead of payload. “With agentic video understanding, we don’t give the model the entire video. We give the reference to the video” — and the model decides what to pull. Three tools are named:
get_transcript(cheap, coarse, usually first),get_frames(with the model specifying which frames and at what frames-per-second — “a great way of getting either a very global or localized perspective”), andget_audio. - It is an explicit agentic loop. “The model first thinks about which tools it might want to use to process this video… It runs those tools — I mean, this is an agentic loop — and it gets an observation in return, frames for instance. And this information is then given back to the model where it can decide to do another loop. And then we have this very traditional agentic loop of thinking, acting, observing, and looping until it finally arrives at the answer.”
- The worked trajectory. Pull the transcript first to locate roughly what happens where; notice something at the five-minute mark; then re-sample that region at a higher frame rate to see it properly. Variable FPS is the mechanism by which the agent trades breadth for depth where it matters.
- The claim that makes it interesting. “Not only does it reduce the number of tokens it really needs, the performance increases — because it can zoom in on certain functions and really pay attention to the things in the video that are actually important to the query.” Cost and accuracy move together rather than trading off.
Visual canon
The explainer is carried by diagrams that build up on screen. The narration names the tools but not their signatures, and rounds the token count. Each entry below is a diagram in its fully built state, transcribed from the still. Gemini’s machine reading was corrected against the image: it misread the on-screen URL and two of the transcript timestamps. All 15 build states are in the manifest, raw/videos/agentic-video-understanding-in-gemini.stills.md.
1 · The naive path and its cost
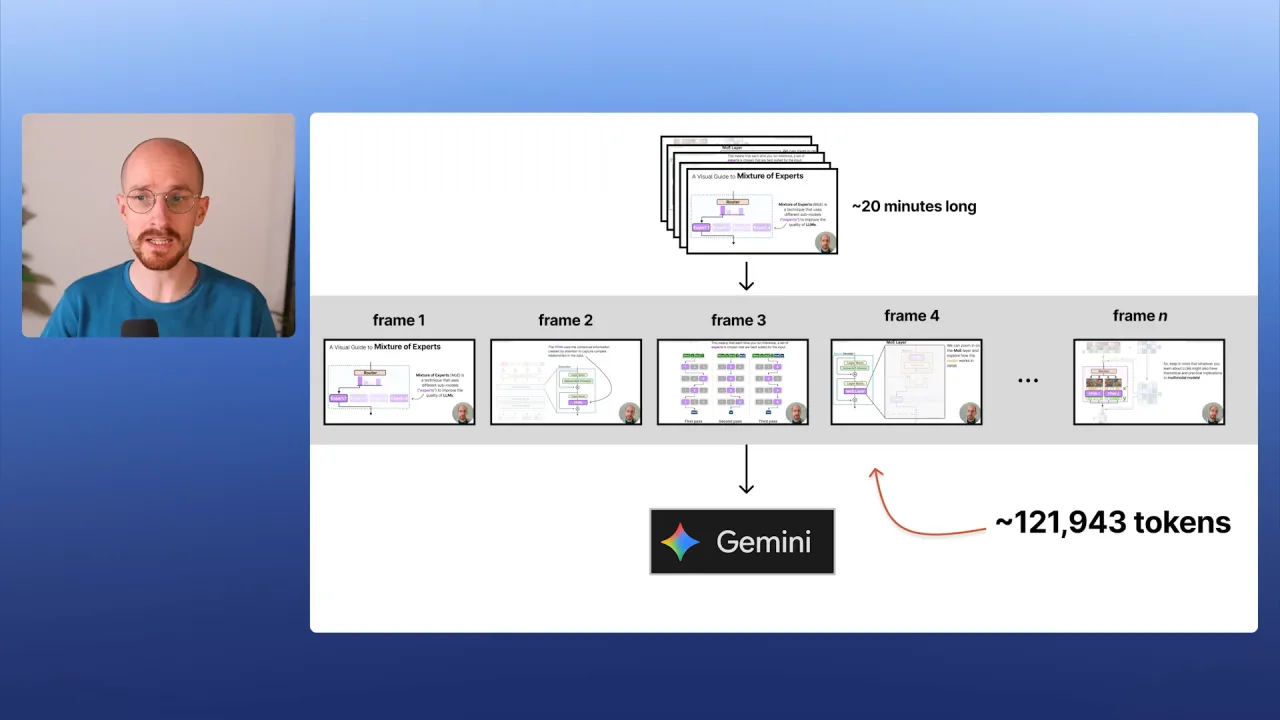
Still at 0:40 from Google for Developers, “Agentic video understanding in Gemini”.
A stack of slides labelled ~20 minutes long → frame 1 · frame 2 · frame 3 · frame 4 · … · frame n → Gemini, with an arrow from the frame row to ~121,943 tokens.
Still vs. transcript: the narration says “more than 100,000 tokens”. The slide gives the figure, ~121,943 tokens, and the size of the example, a ~20-minute video: about 100 tokens per second of video.
2 · Naive processing versus agentic video understanding
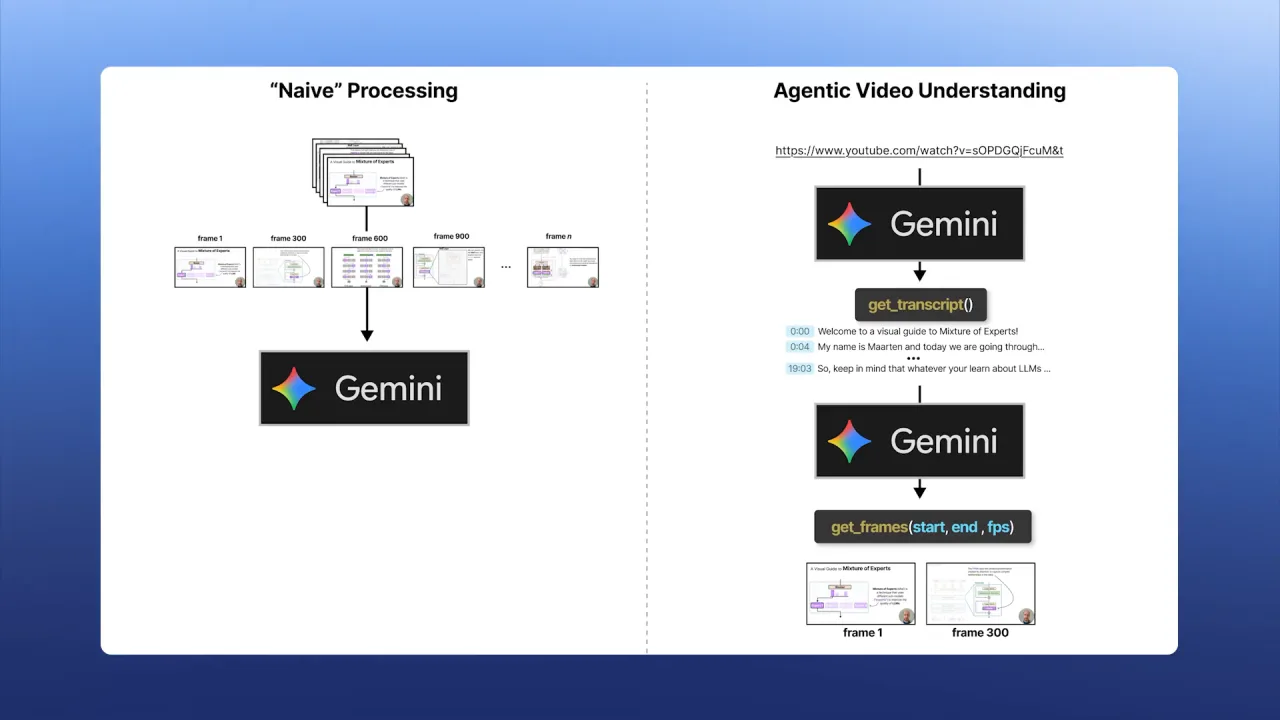
Still at 1:52 from Google for Developers, “Agentic video understanding in Gemini”.
Two columns. “Naive” Processing: the frame row (frame 1, frame 300, frame 600, frame 900, …, frame n) → Gemini. Agentic Video Understanding:
https://www.youtube.com/watch?v=sOPDGQjFcuM&t→ Gemini- →
get_transcript(), which returns timestamped lines:0:00Welcome to a visual guide to Mixture of Experts! ·0:04My name is Maarten and today we are going through… ·19:03So, keep in mind that whatever your learn about LLMs … - → Gemini →
get_frames(start, end, fps), which returns just frame 1 and frame 300.
Still vs. transcript: the narration says the model is given “the reference to the video”. The slide shows that the reference is a plain YouTube URL, and that the example input is a ~19-minute “visual guide to Mixture of Experts” (its transcript opens “My name is Maarten”): the same ~20-minute video costed in diagram 1. It gives get_frames its full signature, and shows the agent coming back with two frames instead of the whole row.
3 · The loop
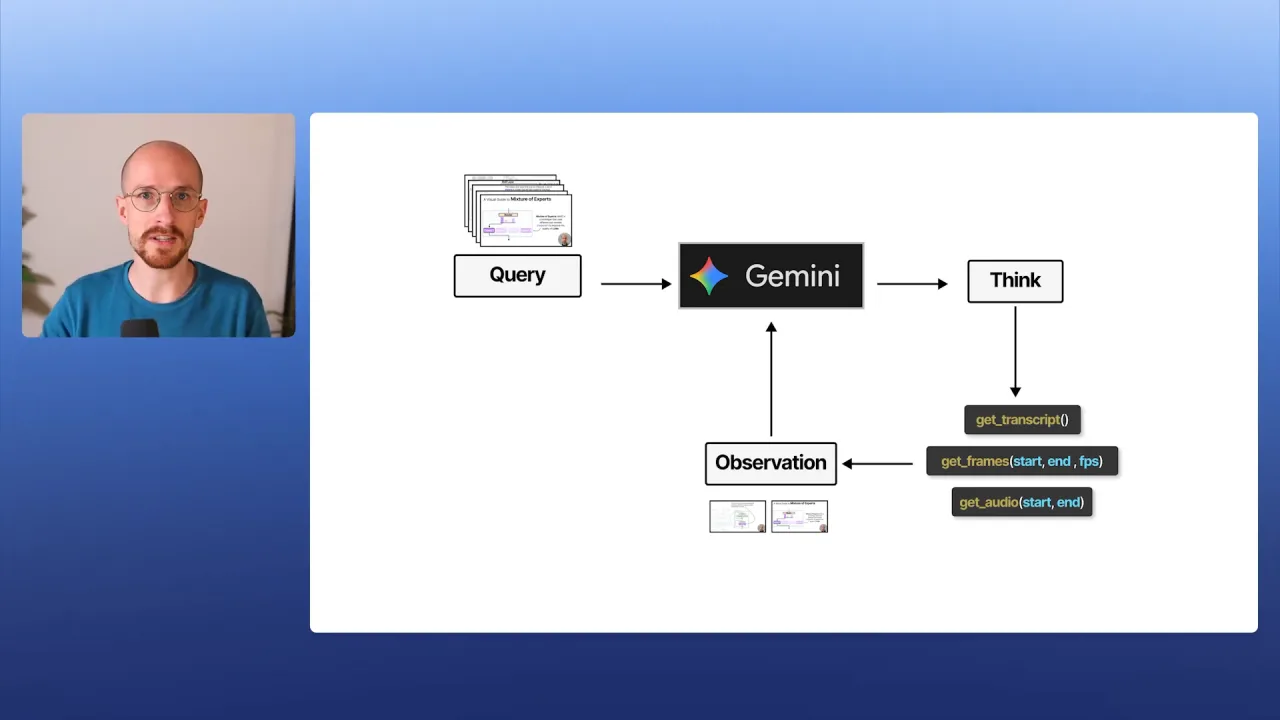
Still at 2:50 from Google for Developers, “Agentic video understanding in Gemini”.
Query (with the video’s slide stack) → Gemini → Think → three tools: get_transcript(), get_frames(start, end, fps), get_audio(start, end) → Observation (two frame thumbnails) → back into Gemini.
Still vs. transcript: the narration walks through thinking, acting and observing. The slide pins down the tool signatures. get_audio takes a (start, end) window, so audio is fetched by segment, like frames. get_transcript() takes no arguments; in diagram 2 it returns lines spanning the whole video, from 0:00 to 19:03.
Why this matters to the wiki
1. It is a modality-crossing instance of the wiki’s central retrieval claim. The corpus establishes at length — in the RAG synthesis, in agent-harness’s context layer, in knowledge-architectures-for-llm-agents — that stuffing a context window is inferior to letting an agent fetch selectively, and that this holds even as windows grow. Every one of those sources argues it over text. This argues it over video, where the token economics are an order of magnitude harsher and the tools are physically different (frame sampling, audio extraction), and reaches the same conclusion. Cross-modality convergence is worth more than another text instance.
2. It is the tightest available illustration of latent-versus-deterministic computation. Tan, five weeks earlier, claims that confusing the two “causes every agent failure I’ve ever seen”: judgment belongs in latent space, exact retrieval belongs in code. Agentic video understanding is that rule applied to perception — what happens at 5:03 is not something to infer from a subsampled global view, it is something to go and fetch at high FPS. Neither source cites the other; they are the same principle at different altitudes.
3. Variable-FPS sampling is a concrete instance of an agent controlling its own resolution. Karten’s expressibility argument is that a harness should expose primitives the model can drive rather than a fixed control flow — and that QM’s win was “pushing that decision into the agent itself rather than the harness.” Choosing frames-per-second per region is exactly that pattern in a perceptual setting: the harness does not pick a sampling rate, the model does, per query and per region.
Dynamic-capabilities reading
digital-seizing/rapid-prototyping is the only cell that genuinely applies: this is a shipped capability announcement aimed at developers, whose function is to let builders try a cheaper architecture immediately. The source is otherwise outside the Warner & Wäger lens — it is a technical mechanism, not an account of organisational transformation — and the tagging is kept deliberately thin rather than stretched, per the schema’s guidance not to force sources into the vocabulary.
Linked entities and concepts
- Entities: Google DeepMind (the speaker’s affiliation and the model’s origin), Google (the developer channel and Gemini).
- Sources: Yao et al. 2022, ReAct (the reason–act–observe loop, here applied to video) and Chopra 2026, Headroom (reducing what reaches the context window, there for text).
- Concepts: react-reasoning-acting (the loop, narrated in ReAct’s own vocabulary), agent-harness (tool design and context economy), ai-agents (tool-driven selective perception), foundation-models (a capability of the Gemini Flash line), document-intelligence (extracting structure from an unstructured artifact by targeted retrieval).
- Dangling (single-source mention, deferred): Maarten Grootendorst, Gemini 3.7 Flash / 3.6 Flash / 3.5 Flash-Lite. Promote on a second citing source per the author-entity promotion rule.
Debates and supersession
- No numbers. The performance claim — that accuracy increases while tokens fall — is asserted without a benchmark, a baseline comparison or an error bar, in a three-minute vendor explainer. The mechanism is plausible and consistent with the wiki’s text-domain evidence, but the wiki should carry it as a vendor claim about its own product, not as a measured result. The linked resources page is an ingest target if it carries evaluation data. (2026-10-01: it does carry figures, “up to 88% fewer total tokens than static processing for long-form content” and about 7% higher quality on long-form content, but no published method. The docs page is still an ingest target, not a source.)
- Tooling note (2026-10-01, a measurement in this repo, not a source). The wiki’s stills pipeline ran the capability on an exhaustive task, “list every visual”, rather than a targeted question. Agentic processing cost 653,588 tokens on this 3:19 video, against 19,680 for static processing. On a 29-minute talk it failed with “Model generated too many tool calls” (
.claude/skills/youtube-transcript-skill/SKILL.md). This does not test the vendor claim, which concerns targeted queries on long videos. It does mark the claim’s scope: the savings come from looking at less of the video, so a task that must look at all of it gets none of them. - Open question — what does the agent do when the transcript is misleading? The described trajectory leans on
get_transcriptas the cheap first probe that tells the model where to look. For videos where the salient content is unspoken — a demonstration, a chart, a silent action — the cheap probe points nowhere useful, and the source does not say how the loop recovers or whether it degrades to dense sampling at full cost. This is the obvious failure mode of a coarse-to-fine strategy and it is unaddressed. - Scope note. This is a capability of specific Gemini Flash models, not a general architectural claim about multimodal models. The wiki should not generalise it to “video understanding is now agentic” without further sources.
What was actually ingested
Full 3:19 transcript (auto-generated English captions, 66 segments). The speaker is not named in the audio; the attribution to Maarten Grootendorst and the affiliation to Google DeepMind come from the channel description, as do the specific model versions. The video is heavily diagrammatic: the naive-versus-agentic pipeline comparison is carried visually. The 2026-09-09 ingest took no slide content, so the architecture was described as narrated. On 2026-10-01 the slides were added: three diagrams, read from stills and published in the Visual canon above. This page was the first run of the stills pipeline (CLAUDE.md §Video stills); the other build states of each diagram are in the manifest. The linked resources page was not ingested.